LangChain in 2026: the key to intelligent chatbots with RAG, tools, and unbeatable UX
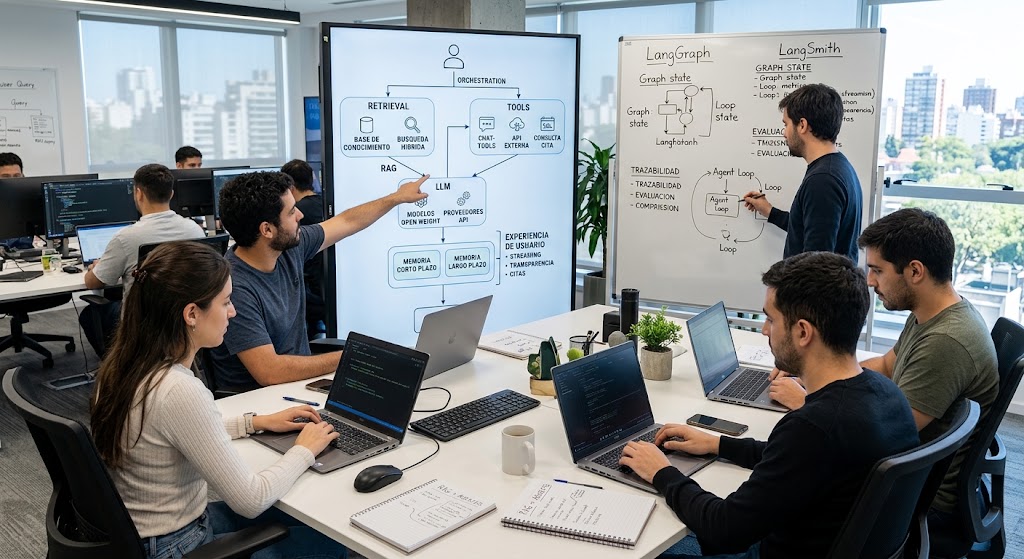
If you've been close to the world of generative artificial intelligence in recent years, you've surely heard about LangChain. It's not a language model, nor a closed product, nor a magic API that solves everything on its own. It's a framework —now established as a de facto standard— for orchestrating everything that surrounds a language model (LLM): information retrieval, use of external tools, memory management, reasoning chains, and above all, the logic that turns a model "that completes text" into an assistant that actually does things.
In this article we're going to review what LangChain is, why it remains relevant in 2026, and what the winning combination is for building intelligent chatbots: RAG (Retrieval-Augmented Generation), chat-tools (tools that the model can invoke), and a user experience that doesn't frustrate anyone.
What exactly is LangChain?
LangChain is an open source framework (with SDKs in Python and JavaScript/TypeScript) designed to build applications on top of LLMs in a modular way. Instead of writing loose prompts and direct calls to an API like OpenAI's, Anthropic's, or open weight models like Llama or Mistral, LangChain gives you abstractions to:
- Chain reasoning steps (chains): for example, first summarizing a document, then classifying it, and finally generating a response.
- Connect the model with external data sources (retrievers, vector stores) to do RAG.
- Give the model "hands" through tools it can decide to invoke: search the web, query an internal API, execute code, write to a database.
- Maintain memory of the conversation, whether short-term (the current session) or long-term (user preferences, history).
- Orchestrate agents, that is, systems where the LLM decides what steps to take and in what order, instead of following a 100% predefined flow.
Over time, the ecosystem expanded with LangGraph, specifically designed to model these flows as state graphs —very useful when the chatbot needs conditional logic, verification loops, or multiple agents collaborating—, and LangSmith, the observability and evaluation layer that lets you see what's happening "inside" the agent: what prompt was generated, what tool was called, how long it took, where it failed.
This separation between "model reasoning" and "application orchestration" is what turned LangChain into such a widely used piece: it doesn't matter which LLM is trendy this quarter, your product's logic can remain relatively stable.
Why a chatbot "with just an LLM" is no longer enough
A language model, no matter how powerful, has structural limitations:
- Frozen knowledge: it was trained up to a certain date and doesn't know what happened in your company last week.
- Hallucinates: when it doesn't know something, it often invents a convincing answer instead of admitting it doesn't have the information.
- Can't act on its own: it can't query your database, schedule a meeting, or charge a payment unless someone explicitly gives it that capability.
- Has no persistent memory unless you build it for it.
That's why a truly "intelligent" chatbot isn't just an LLM with a well-written prompt. It's a system made up of at least three layers: context retrieval (RAG), action capability (tools), and an experience layer that makes all of this feel natural to the person on the other side.
RAG: the chatbot's external memory
RAG (Retrieval-Augmented Generation) is the technique that solves the "frozen knowledge" problem. Instead of relying solely on what the model learned during training, the system searches for relevant information in its own knowledge base —documents, support tickets, internal policies, product catalogs— and injects it into the model as context before generating the response.
The typical flow with LangChain looks like this:
- Documents are split into fragments (chunking) and converted into embeddings.
- Those embeddings are stored in a vector database (Chroma, Pinecone, Weaviate, pgvector, among others).
- When a user query arrives, the most relevant fragments are searched for via semantic similarity.
- Those fragments are passed to the LLM along with the original question, so it can answer based on real, verifiable information.
What's interesting about RAG isn't just that it reduces hallucinations: it also allows for citing sources, something key to building trust. A chatbot that says "according to the return policy updated in March, you have 30 days" is much more trustworthy than one that answers confidently but without being able to justify where that information comes from.
By 2026, RAG implementations have matured quite a bit compared to the first experiments: it's common to combine semantic search with keyword search (hybrid search), apply re-ranking to prioritize the truly relevant fragments, and even use "agentic" RAG, where the model itself decides how many searches to perform and with what terms, instead of a single fixed query.
Chat-tools: when the bot stops just talking and starts doing
If RAG gives the chatbot knowledge, tools give it action capability. This is what separates an informative chatbot from an assistant that resolves tasks end to end.
With LangChain, defining a tool is fairly straightforward: you describe what it does, what parameters it needs, and the model —following the "function calling" or "tool calling" pattern now natively supported by models like GPT, Claude, or Gemini— decides in real time whether it needs to use it and with what arguments.
Typical examples of chat-tools in a production chatbot:
- Checking the status of an order in the e-commerce system.
- Verifying schedule availability and booking an appointment.
- Running a web search for real-time information.
- Generating a support ticket in the internal system.
- Performing calculations or SQL queries on a database.
The key is that the model doesn't execute the action directly on the real world: it decides what it wants to do, and it's your code that validates, executes, and returns the result. This provides control, security, and the possibility of adding human confirmation layers for sensitive actions (such as processing a payment or canceling a subscription).
This is where LangGraph shines especially: it allows explicitly modeling flows where the agent might need several chained tools, ask the user for confirmation before executing a critical action, or retry if a tool fails.
UX: the ingredient that's almost always underestimated
Here comes the part that many technical teams leave for last, and yet it often determines whether a chatbot feels "intelligent" or simply frustrating:
- Response streaming: nobody wants to stare at a blank screen for 8 seconds waiting for the full response. Showing text as it's generated completely changes the perception of speed.
- Transparency about what's happening: if the bot is searching a knowledge base or calling a tool, showing an indicator ("Searching the documentation...", "Checking your order status...") reduces waiting anxiety.
- Graceful handling of "I don't know": a good chatbot admits its limits instead of making things up. Saying "I don't have that information, but I can connect you with a human agent" builds more trust than an ambiguous answer.
- Coherent conversational memory: the bot should remember what was said two messages ago in the same session, without asking you to repeat everything.
- Clear emergency exits: there should always be an easy path to a human when the bot can't solve something.
- Citations and traceability: showing where the information comes from (a link to the document, the exact source) greatly helps build trust, especially in contexts like technical support, healthcare, or finance.
None of these things depend on the language model you choose. They depend on how you design the application around it, and that's exactly the terrain where LangChain (along with LangGraph for flow and LangSmith to observe what's happening) provides the necessary structure.
How do we put all this together in practice?
A typical, realistic stack in 2026 for this kind of chatbot relies on:
- Data ingestion and processing: pipelines that take documents, tickets, FAQs, or internal databases, clean them, split them into reasonable chunks, and generate embeddings.
- Vector database + hybrid search: to retrieve relevant context by combining semantic similarity and keyword matching, with re-ranking when the volume of documents is large.
- Orchestration with LangChain/LangGraph: the decision graph defines when to do RAG, when to call a tool, when to ask the user for confirmation, and when to simply respond.
- Well-defined tools layer: each tool with a clear input/output schema, its validations, and its security limits (rate limiting, permissions, sandboxing when executing code).
- Language model(s): many current implementations use more than one model depending on the task —a cheaper, faster one to classify intent, a more powerful one to generate the final response—, something LangChain facilitates by abstracting the provider behind a common interface.
- Frontend with streaming and intermediate states: the interface consumes the response token by token and clearly shows when the bot is "thinking," searching, or executing an action.
- Observability and continuous evaluation: with LangSmith (or other tracing tools) real conversations are reviewed, RAG failures are detected (irrelevant fragments retrieved), errors in tool usage are found, and prompts or the retrieval strategy are adjusted based on concrete data, not just intuition.
The combination of these layers is what really defines the final quality. A chatbot with a state-of-the-art model but without good RAG will hallucinate. One with perfect RAG but without tools will just answer questions without being able to proactively solve anything. And one with all of that technically well solved, but with bad UX, ends up generating more frustration than value.
Conclusion
LangChain isn't a silver bullet, but it does offer the necessary scaffolding to avoid reinventing the wheel every time an application is built on top of LLMs. The key to an intelligent chatbot in 2026 isn't choosing the biggest model on the market, but designing the orchestration well: giving it reliable external memory with RAG, real action capability with tools, and a user experience that makes all that technical work feel simple, transparent, and human. When those three pieces fit together, the result stops being "just another chatbot" and becomes an assistant that people actually want to use.
Comments
Be the first to comment.